Home / Network & Observability
DNS Resolution Failure Diagnosis: A Practical Guide for IT Administration and Keeping Systems Running
DNS is the silent backbone of everyday IT administration and keeping systems running. When it breaks, applications stall, certificates fail, and users see cryptic errors. A disciplined approach helps you trace the path from the client, through the resolver, into authoritative records, and finally to upstream dependencies. This article explains that path and shows How to troubleshoot DNS resolution failures across client and server layers with repeatable checks, safe fixes, and observability you can maintain long term.
Understand the resolution path before you change anything
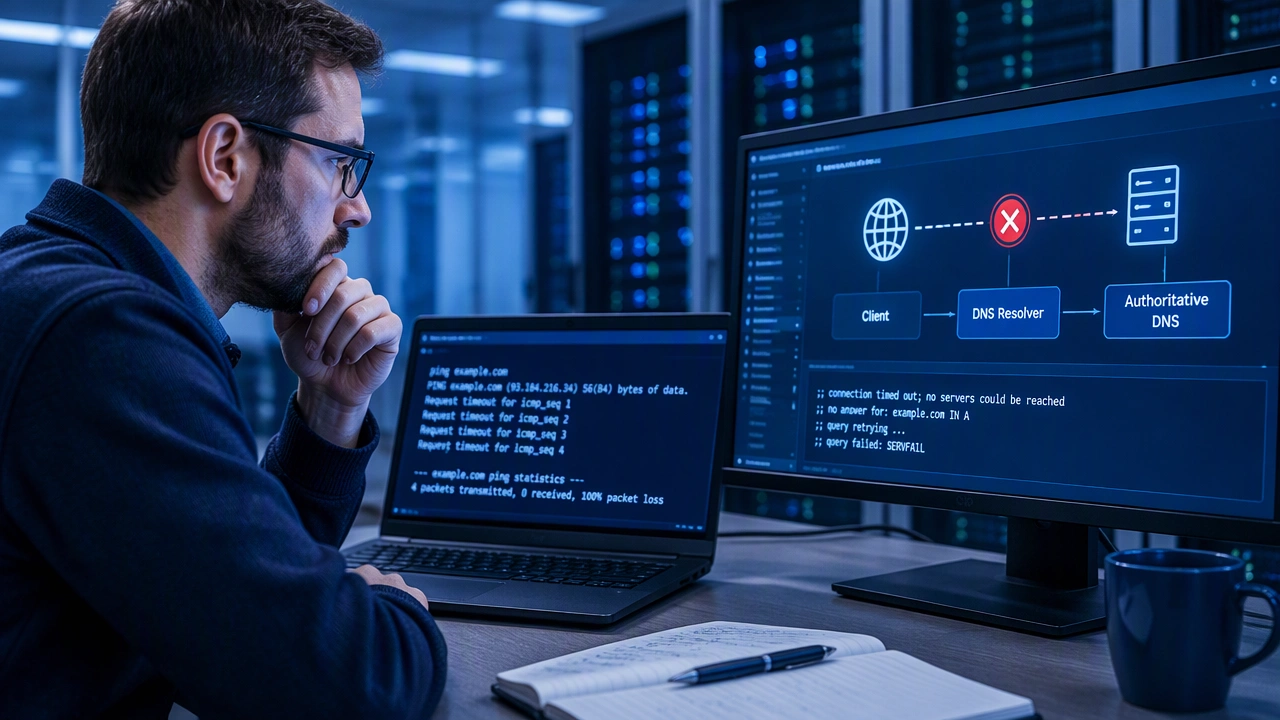
When an application requests a name, the client operating system checks local hints, then asks the configured resolver. That resolver may be an internal forwarding server, a public recursive service, or both. The resolver walks caches, checks root hints, asks the appropriate top level domain servers, and reaches the authoritative servers for the zone. Only then does it return an answer. Failures can occur at any hop, and the symptom is often identical: the name does not resolve.
Before changing settings, note the exact failing name, the client host, the resolver in use, and the time of the failure. That context prevents guesswork and helps you compare healthy and broken paths.
Start at the client and verify the basics
Begin with the simplest facts. Confirm the client has a usable IP address, a correct subnet mask, and a working default gateway. Check that the system is pointing to the intended resolver. On Linux, review /etc/resolv.conf and any systemd resolved or NetworkManager configuration. On Windows, use Get-DnsClientServerAddress and ipconfig /all. On macOS, use scutil –dns. Many outages trace back to a misconfigured adapter, a stale VPN split tunnel, or a container with no DNS settings at all.
Flush the client cache after you confirm configuration. On Windows, run ipconfig /flushdns. On Linux with systemd resolved, run resolvectl flush-caches. On macOS, run sudo dscacheutil -flushcache and sudo killall -HUP mDNSResponder. A stale negative cache entry can block a recently fixed zone from resolving.
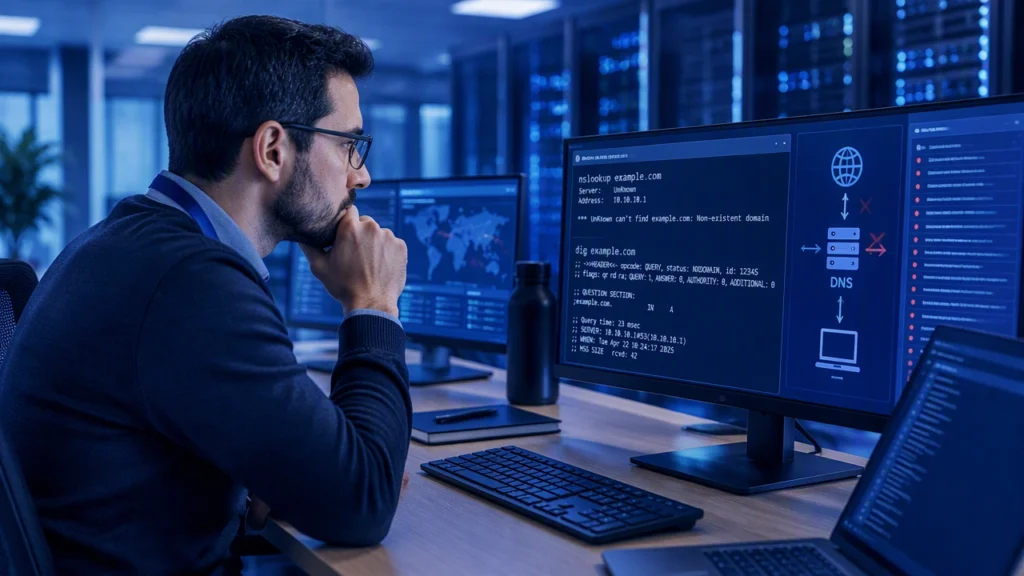
Use targeted queries to isolate the issue. Try a direct query to the configured resolver, then to a well known public resolver, then to the authoritative server itself if possible. For example, use dig or nslookup to request the exact record type that the application needs. Compare the answers. If the name resolves against the public resolver but not your internal resolver, focus on internal forwarding, split horizon rules, or firewall rules between the resolver and the internet.
Inspect the resolver and caching layer
Resolvers often hide the real cause. If you run an internal recursive resolver, check whether it can reach the internet or your forwarders. Verify that UDP and TCP port 53 are allowed outbound, and that any firewall or NAT does not break response routing. If the resolver uses DNS over TLS or DNS over HTTPS, confirm the certificates are valid and that time is correct on the resolver. Clock skew breaks TLS handshakes and makes DNSSEC validation fail.
Review logs for SERVFAIL, REFUSED, and timeout entries. If you see frequent SERVFAIL, test DNSSEC validation. Use dig with +dnssec and +cd to compare validated and non validated responses. If validation fails, check that the resolver has correct time, can reach the parent and child zones, and has the needed trust anchors. If you operate split horizon DNS, ensure that internal clients never leak internal names to public resolvers and that your split matches the source networks exactly.
Measure latency and failure rates from the resolver. Export resolver metrics to your monitoring stack, including queries per second, cache hit ratio, average response time, and failure codes. A sudden drop in cache hits often points to a broken forwarder or a change in upstream reachability.
Check upstream records, zones, and dependencies
If the resolver looks healthy, move upstream. Confirm that the authoritative servers are reachable and responding. Use dig to query the NS records for the zone and then query those servers directly. Verify SOA serial numbers and last modified times to ensure you are looking at the current version of the zone. Confirm that glue records at the parent are correct for any delegation you control.
Examine the specific record type and name you need. Many outages involve a missing A or AAAA record, a stale CNAME chain, or an expired service alias. Check TTL behavior and whether a recent change lowered TTLs for a migration but left them low. If the name points to a load balancer or CDN, verify that the target endpoint is healthy and that any DNS based health checks are not marking it down.
Do not forget service discovery and internal zones. Kubernetes CoreDNS, Consul, and other systems can shadow or extend standard DNS. If only some pods or nodes fail, look at per node resolv.conf content, ndots settings, search domains, and whether the internal DNS service is healthy and replicated.
Use a layered troubleshooting workflow
A simple, repeatable workflow saves time.
- Reproduce: Capture the exact name, record type, client host, and resolver. Record timestamps.
- Client: Check adapter settings, VPN state, and local firewall. Flush caches.
- Resolver: Query the configured resolver directly. Compare to a public resolver and the authoritative server.
- Upstream: Verify NS reachability, zone content, CNAME chains, and DNSSEC status.
- Dependencies: Validate load balancers, CDNs, service discovery, and certificate provisioning that relies on DNS.
- Observe: Add or review logs, metrics, and traces so the next incident is faster to diagnose.
When you find the broken hop, apply the smallest safe change. Examples include correcting a resolver address, reopening port 53, fixing a forwarder, correcting a split horizon rule, updating a zone record, or restoring a service discovery health check.
Prevent repeat failures with observability and process
After recovery, harden the environment. Monitor DNS from both internal and external vantage points. Track success rate, latency, and error codes for common names your organization depends on. Alert on changes in TTL, record values, and NS sets for critical zones. Keep DNS changes in version control and require peer review. Schedule regular audits of resolv.conf across servers and containers, and include DNS checks in your change validation and deployment runbooks.
DNS problems feel mysterious only when you cannot see the path. By walking the path from client to resolver to upstream, recording what you observe at each step, and instrumenting the system for ongoing visibility, you turn a vague outage into a solvable sequence. That is how you practice How to troubleshoot DNS resolution failures across client and server layers in a calm, reliable way that keeps services running and users productive.