Home / Network & Observability
Linux disk full troubleshooting: an evidence-based guide for IT administration
In IT administration, a disk-full alert is common, but the right response is not to delete files at random. Evidence-based diagnosis starts with confirming the problem, identifying the affected filesystem, and then narrowing the scope from the mount point to the directory or file that is consuming space. This article walks through that process in order, with commands you can trust and checks that avoid common pitfalls.
Confirm the problem and the target filesystem
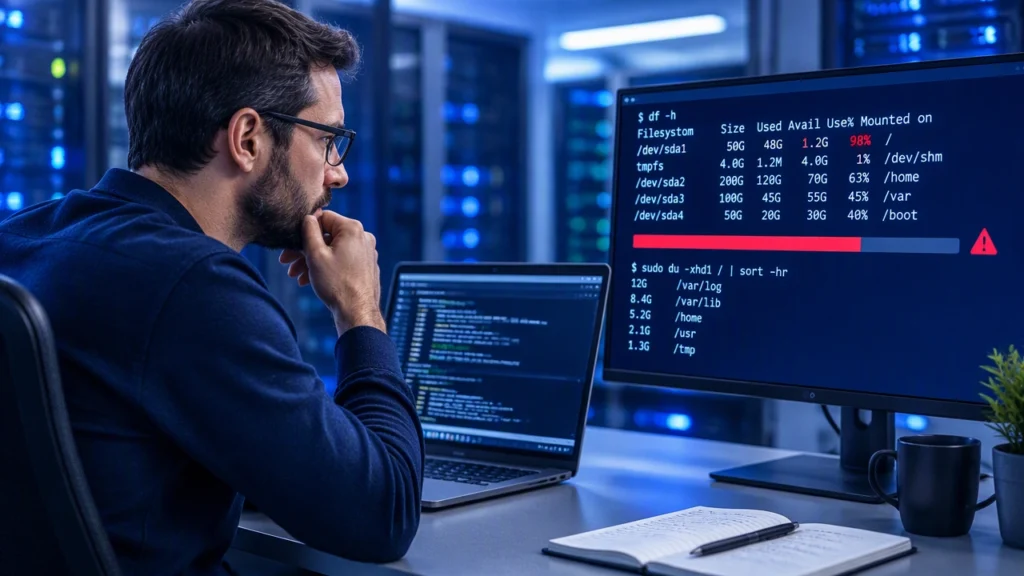
Start by confirming that the alert is current and that you are looking at the correct mount point. Use df -h to review space usage across all mounted filesystems. Pay attention to the Use% column and the Mounted on path. A typical threshold for investigation is around 85–95%, but the immediate trigger should be the alert itself and any symptoms such as write failures, slow logins, or application errors.
If your environment uses logical volumes, also run df -hT so you can see filesystem types and verify whether the full path is a mount point or a directory that lives inside a larger filesystem. Many outages happen because the team cleans the wrong path.
Rule out the most common red herrings
Before you hunt for large directories, rule out two frequent issues that make a filesystem appear full even when no visible files are growing.
- Deleted but still-open files: If a process holds a deleted file open, the space is not released until the file handle closes. Check with lsof +L1. You may see large entries marked as deleted. Restarting the responsible service or truncating the file descriptor usually reclaims the space immediately.
- Inode exhaustion: A filesystem can be full because it ran out of inodes, not blocks. Run df -i to check inode usage. If Use% is near 100 while block usage looks normal, you likely have millions of small files, often in caches, spools, or temporary directories.
Find the directory that is actually growing
Once you confirm which mount point is full, the next step is to find which directory is causing disk full on Linux. Start high and go low. From the root of the affected mount point, run du -h –max-depth=1 to see totals for top-level directories. Sort the output if needed, or pipe it through a pager for readability.
Then descend one level at a time into the largest directories. For example, if /var is large, check /var/log, /var/tmp, and /var/lib. Keep narrowing until you see a single directory that accounts for most of the growth. At that point, list the largest files with ls -lhS or find . -maxdepth 2 -type f -size +100M -exec ls -lh {} ; to pinpoint exact files.
This approach is safer and faster than deleting broadly. It also gives you evidence you can share in a change record or incident ticket.
Check common growth hotspots
If you are unsure where to look first, focus on paths that often grow fast in production:
- Logs: /var/log, application logs, and container logs under /var/lib/docker/containers or /var/lib/containerd. Look for verbose debug levels, repeated errors, or large rotated files that were not compressed.
- Package and image caches: On Debian or Ubuntu, /var/cache/apt/archives. On RHEL or Fedora, /var/cache/dnf. On systems with Snap, /var/lib/snapd/cache. On container hosts, unused images and layers can add up quickly.
- Temporary data: /tmp and /var/tmp can accumulate after failed jobs, builds, or uploads.
- User data and backups: Home directories and ad-hoc backup copies in /opt or /srv are common culprits in smaller environments.
- Journal logs: If you use systemd, journalctl –disk-usage can show a surprisingly large journal that needs size limits.
Use safe cleanup steps
After you identify the target, clean up in a controlled way. For logs, prefer truncation over deletion if the file is open by a service. For example, > /var/log/app/app.log releases space without requiring a restart. If you delete a log that a service is still writing to, the space may not free until the service is restarted.
For caches, use the package manager’s own cleanup commands. For systemd journals, set a size limit and vacuum old entries. For containers, remove unused images and prune build cache. Always verify after each step with df -h and, if relevant, df -i.
Automate and prevent the next occurrence
Evidence-based troubleshooting should lead to prevention. Add monitoring that alerts on both block usage and inode usage per mount point. Track growth trends for critical directories. Set log rotation policies that match your workload, and review them after incidents. If a service repeatedly fills a disk, adjust its retention, lower its verbosity, or move its data to a dedicated volume with its own limits.
Finally, document the mount point, the directory you cleaned, and the process that caused growth. In IT administration, the value of a fix is multiplied when it is repeatable and understood.